Back to Eximietas Software

Digital & Intelligence Engineering · Data for better learning

Synthetic Data

Purpose-built data that helps AI systems learn when reality is scarce, private, or expensive.

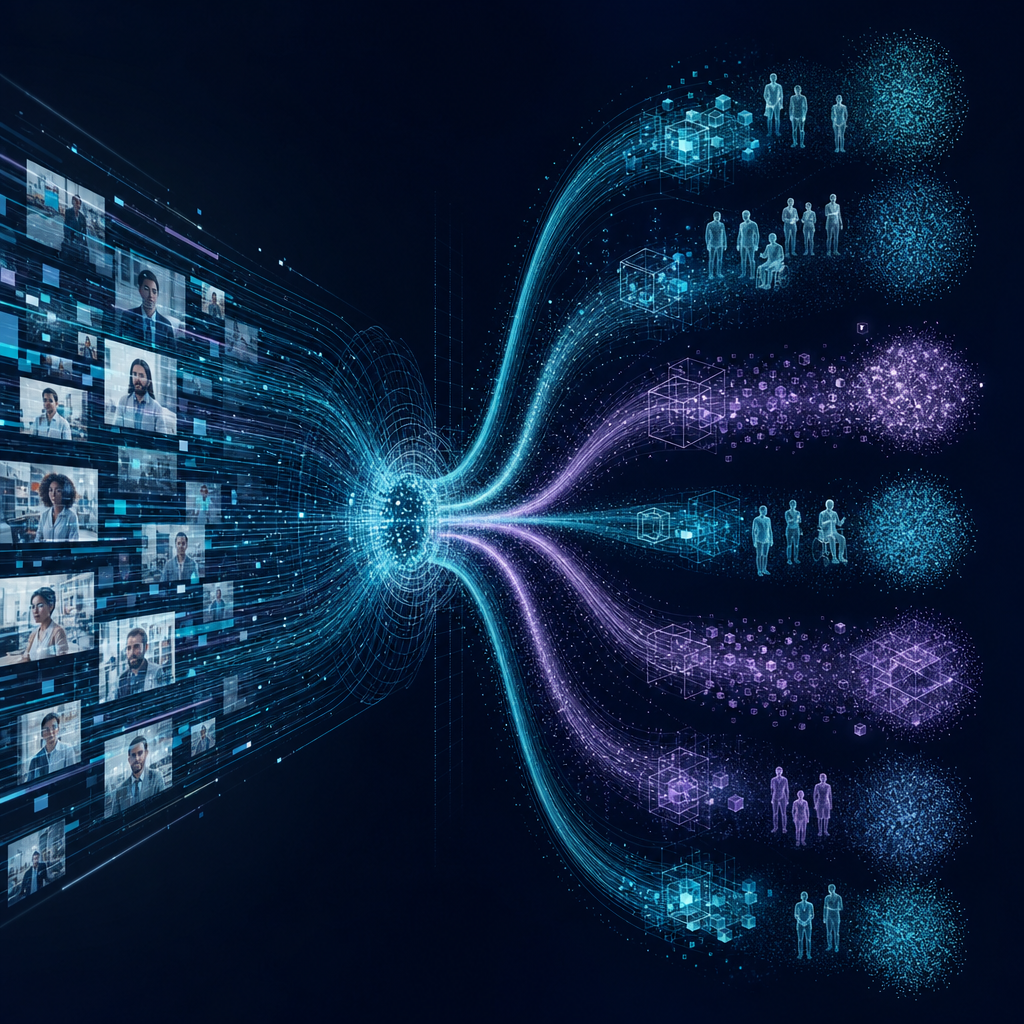
Synthetic data pipeline generating privacy-safe enterprise datasets and rare edge-case scenarios
Privacy-safe synthetic data systems

The work

Engineering that holds up beyond the demo.

We engineer synthetic data that mirrors the statistical and behavioral properties a system needs without exposing sensitive individuals or waiting for rare events to occur. The work combines generation, privacy controls, scenario design, and utility evaluation so teams can train, test, and experiment with evidence rather than volume alone.

What we help you achieve

  • More representative coverage of rare and high-risk scenarios
  • Lower dependence on expensive or restricted real-world data
  • Safer collaboration and experimentation with sensitive domains
  • Faster training and testing data availability
  • Measured privacy, fidelity, utility, and bias tradeoffs

Detailed capabilities

The work behind a dependable platform.

Explore the engineering areas that take this capability from a first technical decision to a stable, production-ready system.

01

Data Need & Generation Strategy

Synthetic data is designed around the missing signal, risk, or test condition—not produced as generic filler.

  • Identify gaps in coverage, rare events, sensitive fields, long-tail behavior, labels, or environments
  • Choose statistical, rule-based, simulation, generative, augmentation, or hybrid methods for the data type and use case
  • Define fidelity, privacy, utility, diversity, fairness, temporal, and operational acceptance criteria
  • Map source data, generation inputs, constraints, seed/version strategy, consumers, and retention boundaries
02

Privacy-Preserving Data Engineering

Synthetic data only reduces risk when it is tested for disclosure, memorization, and residual identifiability.

  • Profile direct and quasi-identifiers, sensitive attributes, relationships, rare combinations, and membership risk
  • Apply de-identification, suppression, generalization, differential privacy, access controls, and purpose limitation where appropriate
  • Prevent memorization and record copying through model, sampling, constraint, and generation controls
  • Document privacy assumptions, residual risk, data provenance, permitted uses, retention, and approval evidence
03

Scenario, Edge-Case & Simulation Generation

Generated examples are most valuable when they expose the situations real data underrepresents.

  • Generate rare failures, fraud patterns, safety events, boundary conditions, minority cohorts, and adversarial inputs
  • Create synthetic images, scenes, documents, time series, transactions, sensor traces, and labeled variants
  • Use simulators, rules, constraints, physics or domain models, and controllable parameters to create explainable scenarios
  • Balance distributions and preserve meaningful dependencies while avoiding artifacts that a model can exploit
04

Utility & Model Evaluation

The right question is whether synthetic data helps the intended model or test perform on real-world behavior.

  • Compare distributions, correlations, marginal behavior, temporal structure, conditional relationships, and rare-event coverage
  • Measure train-on-synthetic/test-on-real, train-on-real/test-on-real, augmentation lift, calibration, robustness, and subgroup behavior
  • Test for nearest-neighbor exposure, membership inference, attribute inference, memorization, and re-identification risk
  • Review quality with domain experts and record known artifacts, limitations, and decisions about appropriate use
05

Data Products & Lifecycle Governance

Synthetic data becomes reusable when generation, evaluation, access, and provenance are treated as a product.

  • Automate source validation, generation, labeling, quality checks, privacy checks, packaging, and publishing
  • Version datasets, generators, prompts or parameters, source snapshots, seeds, evaluation results, and approvals
  • Serve datasets through controlled exports, catalogs, APIs, sandboxes, test fixtures, or training pipelines
  • Monitor source drift, utility decay, privacy risk, usage, lineage, and retirement across the lifecycle

Technical scope

Engineering detail from reset to runtime.

The work is designed around observable system behavior: what executes first, how resources are controlled, how failures are recovered, and how the platform proves it is ready.

01

Data types & generation

  • Tabular, transactional, time-series, sensor, image, video, text, document, multimodal, and simulation data
  • Statistical, rule-based, augmentation, generative, scenario, and hybrid pipelines with constraints and controllable parameters
  • Labels, metadata, ground truth, conditional generation, rare-event coverage, temporal behavior, and dependency preservation
02

Privacy & risk

  • Identifier and quasi-identifier analysis, de-identification, suppression, generalization, differential privacy, and access boundaries
  • Memorization, record copying, nearest-neighbor exposure, membership inference, attribute inference, and re-identification testing
  • Provenance, permitted use, retention, residual risk, approval evidence, and domain-specific privacy requirements
03

Fidelity & utility

  • Distribution, correlation, conditional relationship, temporal, diversity, bias, and rare-event comparisons
  • Train-on-synthetic/test-on-real, augmentation lift, calibration, robustness, subgroup performance, and downstream task utility
  • Domain review, artifact analysis, acceptance thresholds, limitations, and use-case-specific release decisions
04

Operations & governance

  • Versioned sources, generators, parameters, seeds, datasets, labels, evaluations, packages, and approvals
  • Automated validation, privacy and utility gates, catalogs, APIs, sandboxes, training/test fixtures, and controlled exports
  • Drift, utility decay, privacy posture, access, usage, lineage, incident handling, and retirement monitoring

Services and customer value

Technical work with a business reason.

Every engineering activity is tied to a decision your team needs to make: bring up faster, reduce risk, improve determinism, or prove production readiness.

01

Synthetic data strategy

Technical work

Assess the data gap, sensitivity, rare-event problem, generation method, acceptance criteria, consumer workflow, and governance needed for a useful synthetic data product.

Customer benefit

Teams know where synthetic data will accelerate work and where real data or additional collection is still required.

02

Privacy-aware data generation

Technical work

Generate tabular, time-series, image, text, document, or multimodal datasets with constraints, de-identification, privacy controls, provenance, and disclosure testing.

Customer benefit

Organizations can collaborate and experiment more safely without treating sensitive production records as a default development dataset.

03

Rare-event and edge-case augmentation

Technical work

Create controllable failures, minority cohorts, adversarial cases, safety events, fraud patterns, and labeled scenarios through simulation, rules, augmentation, or generative methods.

Customer benefit

Models and test suites encounter the cases most likely to cause costly misses before those cases appear in production.

04

Utility and fidelity evaluation

Technical work

Compare statistical properties, privacy leakage, downstream model performance, robustness, calibration, bias, diversity, and domain-expert acceptance.

Customer benefit

Teams can defend whether generated data is fit for training, testing, analytics, or prototyping instead of assuming more data means better data.

05

Synthetic data operations

Technical work

Automate source validation, generation, labeling, evaluation, publishing, access, versioning, lineage, drift monitoring, and retirement workflows.

Customer benefit

Synthetic datasets stay reproducible, discoverable, current, and governed as the underlying product and data change.

Why this matters for AI

Intelligence needs a dependable execution layer.

AI development is often constrained by privacy, scarcity, and the long tail of real-world behavior. Synthetic data expands what models can learn and what systems can be tested, but only when its statistical utility, privacy posture, and failure modes are measured against the intended use.

What you take forward

Clear outputs your team can build on.

  • Synthetic data opportunity assessment, use-case map, risk profile, method selection, acceptance criteria, and governance plan
  • Source and schema package with data profile, sensitive-field analysis, constraints, provenance, and quality checks
  • Versioned generation pipeline for selected tabular, time-series, image, text, document, multimodal, or simulation data
  • Scenario and edge-case library with labels, parameters, rare-event coverage, minority cohorts, and adversarial examples
  • Privacy and utility evaluation pack with fidelity metrics, downstream performance, leakage tests, bias review, domain feedback, and limitations
  • Operational handoff with dataset catalog or delivery interface, lineage, approvals, monitoring, retention, and retirement runbook

Capability map

Built across the layers.

The right answer is usually a connected system of decisions, not a single isolated skill.

01

Tabular, time-series, image, text, and multimodal data generation

02

Privacy-preserving synthetic data and de-identification strategies

03

Rare-event, edge-case, and scenario-based augmentation

04

Simulation and digital-environment data creation

05

Statistical fidelity, utility, leakage, and bias evaluation

06

Versioned generation pipelines and governance

Keep exploring

See how the pieces connect.