Back to Eximietas Software

Digital & Intelligence Engineering · Resilient systems for complex products

Microservices & Distributed Systems

Decompose, connect, and operate distributed systems that remain reliable as scale and team ownership grow.

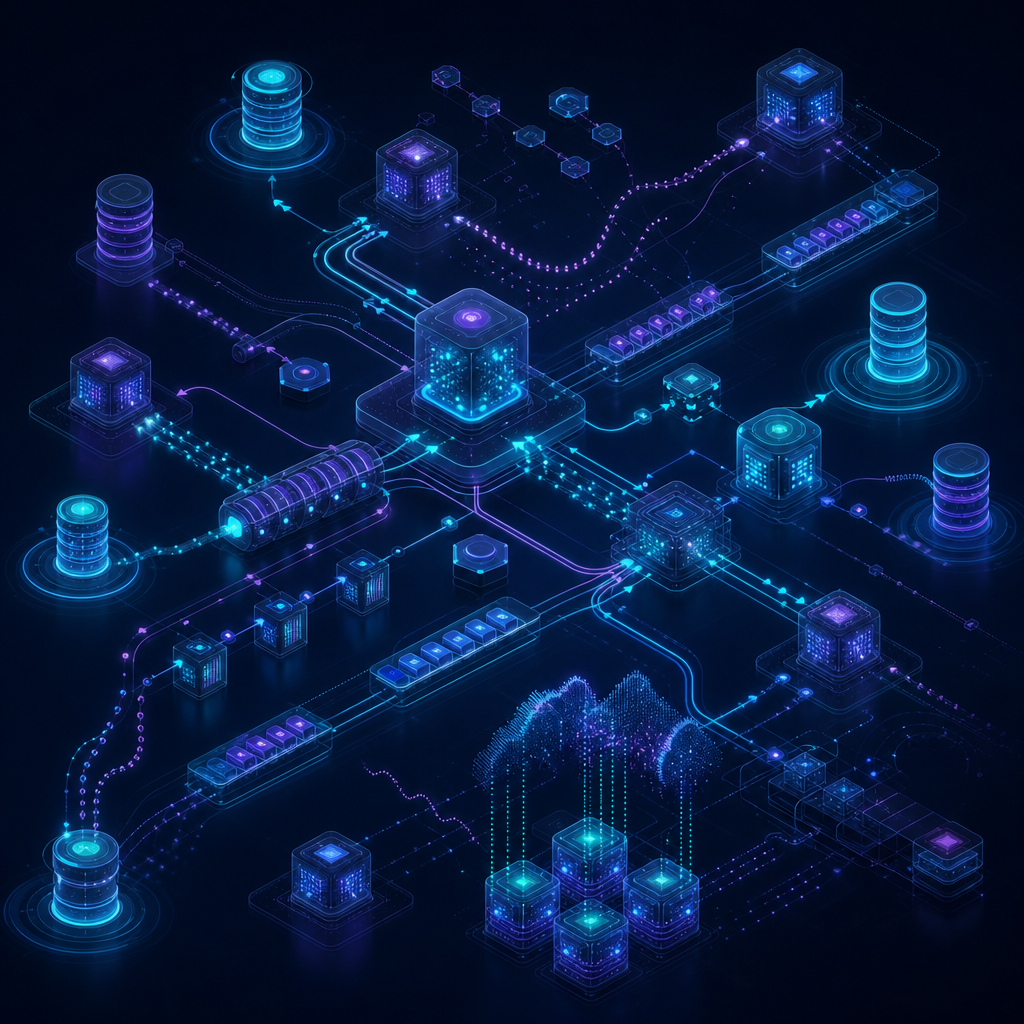
Interconnected microservices with event streams, resilient communication paths, observability traces, and failover layers
Distributed systems built to recover

The work

Engineering that holds up beyond the demo.

We design and modernize microservices and distributed systems for enterprises and product companies managing growing traffic, teams, integrations, and operational complexity. The work covers service boundaries, event-driven systems, communication, resilience, observability, migration from monoliths, and the platform practices that make distributed ownership sustainable.

What we help you achieve

  • Clear service boundaries aligned to domains, ownership, data, and change velocity
  • Reliable communication patterns across synchronous, asynchronous, and event-driven workflows
  • Resilience against partial failure, overload, dependency failure, and network uncertainty
  • A safer path from monolith to distributed architecture through incremental migration
  • Operational visibility with SLOs, traces, metrics, logs, runbooks, and accountable ownership

Detailed capabilities

The work behind a dependable platform.

Explore the engineering areas that take this capability from a first technical decision to a stable, production-ready system.

01

Microservice Decomposition

Create service boundaries that reduce coupling without distributing complexity blindly.

  • Map domains, bounded contexts, workflows, data ownership, team boundaries, and change frequency
  • Identify decomposition seams, service responsibilities, contracts, dependencies, and transaction boundaries
  • Evaluate microservices against modular monolith, serverless, workflow, and other architecture options
  • Define ownership, standards, developer experience, and governance for sustainable service delivery
02

Event-Driven Systems

Use events and asynchronous workflows where they improve scale, decoupling, and business responsiveness.

  • Design events, commands, queues, streams, pub/sub, workflows, consumers, ordering, replay, and retention
  • Define schemas, versioning, idempotency, delivery semantics, deduplication, and dead-letter handling
  • Connect operational, product, data, AI, and partner workflows through reliable event contracts
  • Measure lag, throughput, consumer health, failure, backpressure, and recovery
03

Service-to-Service Communication

Make internal communication secure, discoverable, observable, and safe to change.

  • Choose REST, GraphQL, gRPC, messaging, or workflow patterns based on latency, coupling, and failure needs
  • Implement gateways, service discovery, identity, authorization, tenancy, rate limits, and compatibility
  • Define timeouts, retries, circuit breakers, bulkheads, backoff, fallbacks, and idempotency
  • Provide contract tests, documentation, tracing, dependency maps, and developer tooling
04

Resilience & Operations

Engineer for partial failure because distributed systems are always operating through uncertainty.

  • Model failure domains, overload, dependency failure, network partitions, stale data, and degraded modes
  • Build health checks, graceful degradation, failover, recovery, disaster readiness, and incident playbooks
  • Establish SLOs, SLIs, error budgets, logs, metrics, traces, alerts, dashboards, and service ownership
  • Test resilience with load, failure injection, recovery, rollout, rollback, and capacity exercises
05

Migration from Monoliths

Move toward service-oriented architecture incrementally while protecting product delivery and data integrity.

  • Assess monolith boundaries, coupling, data ownership, release constraints, and high-value migration seams
  • Use strangler patterns, anti-corruption layers, dual reads or writes, events, and coexistence where appropriate
  • Plan data transition, contract compatibility, traffic shifting, cutover, rollback, and decommissioning
  • Measure migration outcomes through reliability, delivery speed, ownership, cost, and customer impact

Technical scope

Engineering detail from reset to runtime.

The work is designed around observable system behavior: what executes first, how resources are controlled, how failures are recovered, and how the platform proves it is ready.

01

Service architecture

  • Domains, bounded contexts, workflows, data ownership, teams, change frequency, decomposition seams, responsibilities, contracts, and transactions
  • Microservices, modular monoliths, serverless, workflows, ownership, standards, governance, and developer experience
02

Events & communication

  • Events, commands, queues, streams, pub/sub, workflows, schemas, ordering, replay, retention, idempotency, delivery, deduplication, and dead letters
  • REST, GraphQL, gRPC, messaging, gateways, discovery, identity, authorization, tenancy, rate limits, compatibility, and contract tests
03

Resilience & operations

  • Timeouts, retries, backoff, circuit breakers, bulkheads, fallbacks, health checks, failover, recovery, degradation, overload, and failure domains
  • SLOs, SLIs, error budgets, logs, metrics, traces, alerts, dashboards, ownership, load, failure injection, rollout, rollback, and capacity
04

Modernization

  • Monolith boundaries, coupling, data ownership, release constraints, strangler patterns, anti-corruption layers, dual reads or writes, events, and coexistence
  • Data transition, compatibility, traffic shifting, cutover, rollback, decommissioning, reliability, delivery speed, cost, ownership, and customer impact

Services and customer value

Technical work with a business reason.

Every engineering activity is tied to a decision your team needs to make: bring up faster, reduce risk, improve determinism, or prove production readiness.

01

Microservice decomposition

Technical work

Map domains, bounded contexts, workflows, ownership, data, change boundaries, contracts, and migration seams before selecting service boundaries.

Customer benefit

Teams gain independent ownership and delivery speed without distributing the wrong responsibilities or creating hidden coupling.

02

Event-driven systems

Technical work

Design events, queues, streams, workflows, schemas, ordering, replay, idempotency, delivery semantics, consumer health, and recovery.

Customer benefit

Products handle asynchronous work, integrations, and scale with less coupling and more visible operational behavior.

03

Resilient service communication

Technical work

Engineer APIs, gateways, discovery, identity, timeouts, retries, circuit breakers, bulkheads, rate limits, fallbacks, tracing, and contracts.

Customer benefit

Partial failures become controlled, observable, and recoverable rather than cascading into customer-visible outages.

04

Monolith modernization

Technical work

Plan and execute strangler, coexistence, data transition, traffic shifting, cutover, rollback, and decommissioning patterns.

Customer benefit

The organization modernizes incrementally while continuing product delivery and protecting data and customer experience.

Fixed-bid project options

Defined scope. Measurable outcomes.

Start with a clearly bounded enterprise engineering program. Each package defines the work, outputs, assumptions, and acceptance criteria before implementation begins.

01Assessment

Distributed Systems Architecture Assessment

Assess a defined product or platform surface for service boundaries, event flows, communication, resilience, observability, and migration risk.

Deliverables

  • Current-state service, dependency, data, and failure map
  • Target service and communication architecture
  • Resilience, SLO, observability, and ownership gap register
  • Prioritized decomposition or modernization roadmap

Acceptance criteria

Stakeholders approve the target boundaries, contracts, failure model, operational controls, priorities, and ownership plan.

02Production pilot

Resilient Microservice Pilot

Implement one representative service or event workflow with production-grade communication, resilience, observability, and deployment controls.

Deliverables

  • Working service, event, or workflow implementation
  • Contract, identity, retry, timeout, and failure-handling configuration
  • Logs, metrics, traces, SLOs, alerts, and runbook
  • Load, failure, recovery, rollout, and rollback evidence

Acceptance criteria

The pilot meets the agreed contract, load, resilience, observability, deployment, and recovery thresholds.

03Scale & hardening

Monolith-to-Services Migration Blueprint

Create an incremental migration plan for a defined monolith boundary, including coexistence, data transition, cutover, rollback, and decommissioning.

Deliverables

  • Migration seam, dependency, and data transition design
  • Strangler, compatibility, traffic-shifting, and coexistence plan
  • Cutover, rollback, reliability, and customer-impact controls
  • Delivery sequence, ownership, investment, and risk roadmap

Acceptance criteria

Engineering and business owners approve the migration sequence, data approach, cutover controls, rollback plan, and success measures.

Why this matters for AI

Intelligence needs a dependable execution layer.

AI-enabled products depend on reliable distributed systems for model calls, retrieval, events, agent tools, user workflows, and feedback loops. We make those services resilient and observable so intelligent features can scale without turning dependency failure into product failure.

What you take forward

Clear outputs your team can build on.

  • Distributed systems assessment with domains, service boundaries, contracts, dependencies, data ownership, failure modes, and migration seams
  • Event and communication package with schemas, workflows, gateways, discovery, identity, compatibility, retries, idempotency, and contract tests
  • Resilience and operations package with SLOs, telemetry, alerts, failure testing, recovery, runbooks, rollout, rollback, and capacity
  • Modernization handoff with strangler, coexistence, data transition, traffic shifting, cutover, decommissioning, ownership, and roadmap

Capability map

Built across the layers.

The right answer is usually a connected system of decisions, not a single isolated skill.

01

Microservice decomposition, bounded contexts, service ownership, and contract design

02

Event-driven systems, queues, streams, pub/sub, workflows, and asynchronous processing

03

Service-to-service communication, API gateways, discovery, identity, authorization, and tenancy

04

Resilience, retries, timeouts, circuit breakers, bulkheads, idempotency, and recovery

05

Migration from monoliths, strangler patterns, coexistence, data transition, and cutover

06

Observability, SLOs, tracing, capacity, deployment, incident response, and platform standards

Keep exploring

See how the pieces connect.