Back to Eximietas Software

Digital & Intelligence Engineering · Governed data for intelligent products

Enterprise Data Products & AI Data Platform Engineering

Turn fragmented enterprise data into trusted, reusable products that power AI and decisions.

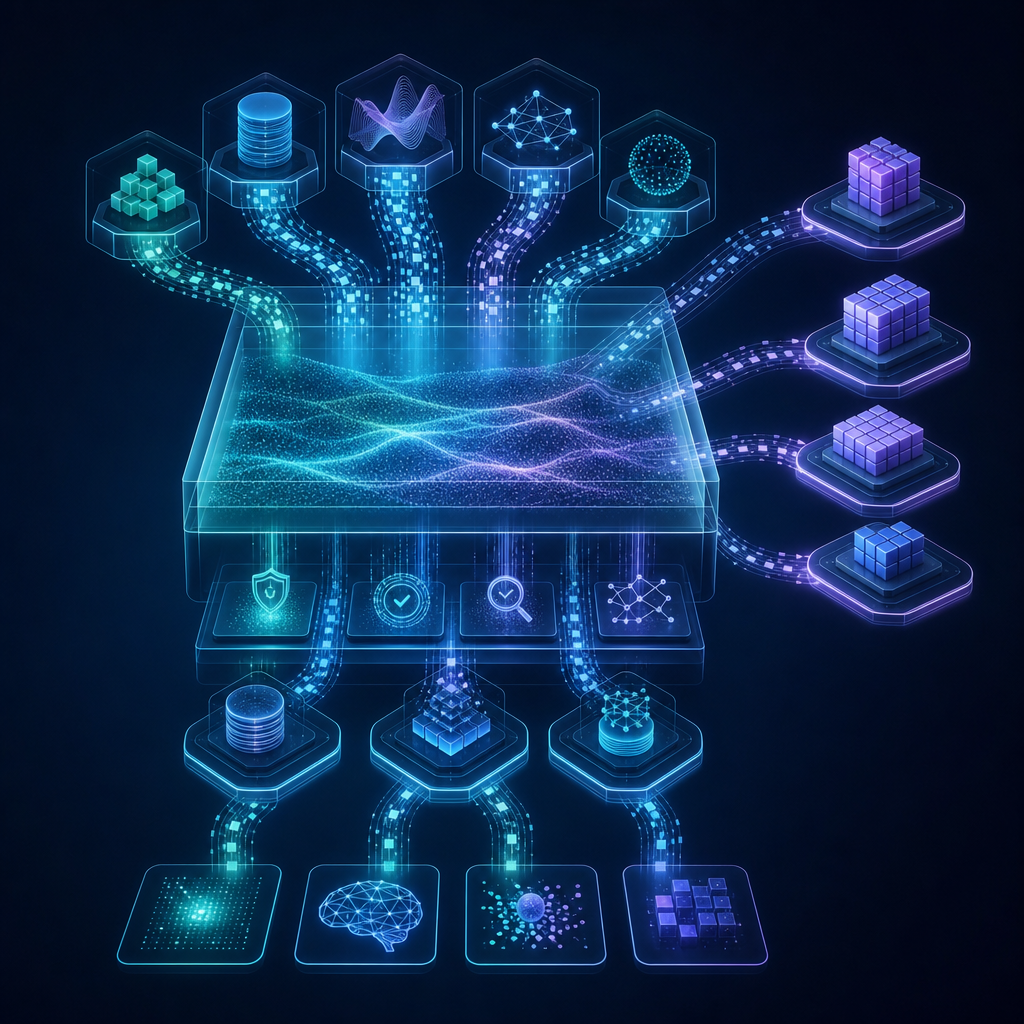
Governed enterprise data domains flowing through a modern AI data platform with quality and lineage controls
Data foundations for intelligent products

The work

Engineering that holds up beyond the demo.

We help large enterprises and AI-enabled product companies create governed data products that are discoverable, reliable, secure, and ready for analytics and AI. We connect domain ownership, lakehouse and warehouse architecture, streaming, data contracts, quality, lineage, feature and vector services, privacy, and platform operations into a data foundation teams can build on.

What we help you achieve

  • Trusted, reusable data products with clear domain ownership and service expectations
  • Faster access to governed data for AI, analytics, product, and operational decisions
  • Higher data quality with visible freshness, completeness, lineage, and contract health
  • Reduced duplication across teams, pipelines, warehouses, features, and knowledge services
  • A scalable AI data foundation that respects privacy, residency, security, and retention requirements

Detailed capabilities

The work behind a dependable platform.

Explore the engineering areas that take this capability from a first technical decision to a stable, production-ready system.

01

Data Product Strategy & Domain Architecture

Make data ownership, boundaries, and consumer expectations explicit before scaling another pipeline.

  • Map priority AI, analytics, product, and operational use cases to data domains and accountable owners
  • Define data product interfaces, contracts, schemas, quality expectations, access policies, and lifecycle
  • Choose lakehouse, warehouse, streaming, event, batch, or hybrid patterns around latency, scale, cost, and control
  • Create a roadmap that sequences high-value domains, platform capabilities, migration risk, and adoption
02

Data Platform & Pipeline Engineering

Build the reliable movement, transformation, and serving paths that make governed data usable.

  • Engineer batch, streaming, event-driven, CDC, and hybrid ingestion with retries, replay, idempotency, and recovery
  • Design transformation, normalization, aggregation, enrichment, partitioning, retention, and schema-evolution patterns
  • Connect source systems, operational applications, warehouses, lakehouses, feature services, vector indexes, and knowledge stores
  • Automate orchestration, testing, deployment, backfills, dependency management, and environment promotion
03

Quality, Lineage & Discoverability

AI and analytics teams need to know whether data is usable, where it came from, and when it changed.

  • Implement freshness, completeness, validity, uniqueness, consistency, volume, distribution, and anomaly checks
  • Capture technical and business metadata, lineage, ownership, usage, classification, provenance, and change history
  • Create catalogs, search, documentation, examples, quality scores, consumer feedback, and incident workflows
  • Define data contracts, quality SLOs, alerting, quarantine, remediation, and release gates
04

AI-Ready Data Services

Prepare the specialized data services that turn enterprise information into useful model context and product signals.

  • Build feature definitions, point-in-time correct serving, offline-online consistency, and training data pipelines
  • Engineer document parsing, metadata, embeddings, vector and hybrid indexes, retrieval, freshness, and access-aware context
  • Support labeled data, evaluation sets, synthetic data, feedback, preference signals, and model observability
  • Connect governed data products to models, agents, analytics, dashboards, APIs, and customer-facing product experiences
05

Privacy, Security & Data Operations

Data products become enterprise-grade when protection, residency, reliability, and economics are built into daily operations.

  • Apply classification, PII detection, masking, encryption, identity, RBAC/ABAC, tenant isolation, residency, and retention
  • Monitor data health, pipeline reliability, resource use, spend, access, policy violations, and consumer outcomes
  • Establish incident, recovery, replay, backfill, deprecation, archival, and retirement procedures
  • Create platform SLOs, support ownership, cost allocation, capacity planning, and continuous improvement

Technical scope

Engineering detail from reset to runtime.

The work is designed around observable system behavior: what executes first, how resources are controlled, how failures are recovered, and how the platform proves it is ready.

01

Data products & domains

  • Use-case and domain mapping, ownership, interfaces, schemas, contracts, quality expectations, access policy, lifecycle, and consumer feedback
  • Lakehouse, warehouse, streaming, event, batch, CDC, hybrid, latency, scale, residency, cost, and control decisions
02

Pipelines & serving

  • Ingestion, transformation, normalization, enrichment, partitioning, schema evolution, orchestration, retries, replay, idempotency, backfill, and promotion
  • Operational systems, warehouses, lakehouses, feature stores, vector indexes, knowledge services, APIs, dashboards, and product integrations
03

Quality & AI readiness

  • Freshness, completeness, validity, uniqueness, consistency, volume, distribution, anomaly, quality SLO, contract, quarantine, and remediation controls
  • Metadata, catalog, lineage, provenance, feature serving, embeddings, retrieval, evaluation sets, labeled data, synthetic data, feedback, and model observability
04

Governance & operations

  • Classification, PII, masking, encryption, identity, RBAC/ABAC, tenant isolation, residency, retention, audit, policy, and data access monitoring
  • Pipeline health, resource, spend, consumer, incident, recovery, replay, backfill, archival, retirement, SLO, support, and capacity planning

Services and customer value

Technical work with a business reason.

Every engineering activity is tied to a decision your team needs to make: bring up faster, reduce risk, improve determinism, or prove production readiness.

01

Data product strategy and domain architecture

Technical work

Map priority use cases, data domains, owners, contracts, quality expectations, platform boundaries, consumer needs, and a sequenced implementation roadmap.

Customer benefit

The organization can invest in reusable data capabilities with clear accountability instead of accumulating disconnected pipelines.

02

Enterprise data platform engineering

Technical work

Build batch, streaming, event, CDC, lakehouse, warehouse, hybrid, orchestration, transformation, serving, and environment-promotion foundations.

Customer benefit

Teams get dependable access to the right data at the right latency without compromising recovery, scale, or operating control.

03

Data quality, lineage, and observability

Technical work

Implement contracts, freshness, completeness, validity, distribution, anomaly, lineage, catalog, provenance, ownership, alerting, and remediation workflows.

Customer benefit

AI and analytics consumers can trust the data because quality and change are visible before they become expensive model or business failures.

04

AI-ready feature and knowledge services

Technical work

Create feature, embedding, vector, retrieval, evaluation, labeled-data, synthetic-data, feedback, and model-observability services with access-aware controls.

Customer benefit

Product and AI teams reuse governed context and signals instead of rebuilding specialized data foundations for every use case.

05

Privacy, security, and data operations

Technical work

Apply classification, PII, masking, identity, residency, retention, audit, SLO, cost, incident, recovery, archival, and retirement controls.

Customer benefit

Data products scale across the enterprise with protection, resilience, and ownership built into their operating model.

Fixed-bid project options

Defined scope. Measurable outcomes.

Start with a clearly bounded enterprise engineering program. Each package defines the work, outputs, assumptions, and acceptance criteria before implementation begins.

01Assessment

AI-Ready Data Product Assessment

Assess one priority business domain, its sources, consumers, quality, ownership, AI readiness, risk, and target data-product architecture.

Deliverables

  • Domain and source inventory with ownership map
  • Data-product contract and quality-SLO proposal
  • AI readiness, privacy, lineage, and platform-gap assessment
  • Prioritized implementation roadmap and investment case

Acceptance criteria

Stakeholders approve the domain boundary, owner, consumer needs, contract, quality targets, risk controls, and sequenced roadmap.

02Implementation sprint

Governed Data Product Implementation

Implement one bounded data product from agreed sources through ingestion, transformation, quality, lineage, access, serving, and handoff.

Deliverables

  • Production data pipeline and environment configuration
  • Schema, contract, quality checks, lineage, catalog, and documentation
  • Access, privacy, retention, monitoring, and incident controls
  • Consumer interface, runbook, and operational handoff

Acceptance criteria

The data product meets the agreed schema, freshness, quality, access, lineage, recovery, and consumer-validation criteria.

03Architecture program

Enterprise AI Data Platform Blueprint

Design the target data platform for AI, analytics, product, and operational consumers across agreed domains and deployment environments.

Deliverables

  • Reference architecture and capability map
  • Data, feature, vector, knowledge, and serving patterns
  • Governance, security, residency, SLO, and operating model
  • Migration, adoption, cost, and capacity roadmap

Acceptance criteria

Architecture, operating, security, cost, and migration decisions are documented, reviewed, and approved by technical and business owners.

Why this matters for AI

Intelligence needs a dependable execution layer.

AI systems are only as dependable as the data foundations behind them. We engineer data products that are owned, observable, governed, and shaped for real model and product workloads so enterprises can move faster without turning poor data quality, privacy gaps, or duplicated platforms into permanent operating cost.

What you take forward

Clear outputs your team can build on.

  • Domain and data-product assessment with owners, consumers, source inventory, contracts, quality, risk, AI readiness, and roadmap
  • Production data platform package with ingestion, transformation, orchestration, batch, streaming, CDC, serving, recovery, and environment promotion
  • Quality and discoverability package with contracts, checks, SLOs, lineage, catalog, metadata, provenance, alerting, and remediation
  • AI-ready services for features, embeddings, vector retrieval, evaluation data, synthetic data, feedback, and model observability
  • Governance and operations handoff with privacy, access, residency, retention, audit, cost, incident, recovery, archival, and retirement controls

Capability map

Built across the layers.

The right answer is usually a connected system of decisions, not a single isolated skill.

01

Data product strategy, domain boundaries, ownership, contracts, and operating model

02

Lakehouse, warehouse, streaming, event, batch, and hybrid data architectures

03

Data quality, observability, lineage, cataloging, metadata, and discoverability

04

Feature stores, vector indexes, knowledge services, and AI-ready data pipelines

05

Privacy, PII, access, residency, retention, encryption, and policy controls

06

Self-service data platform, reusable connectors, orchestration, and release automation

07

Data product SLOs, incident response, cost allocation, and lifecycle management

Keep exploring

See how the pieces connect.