Back to Eximietas Software

Digital & Intelligence Engineering · The factory for intelligence

Enterprise AI Platform Engineering

The platform layer that turns isolated AI pilots into a repeatable enterprise capability.

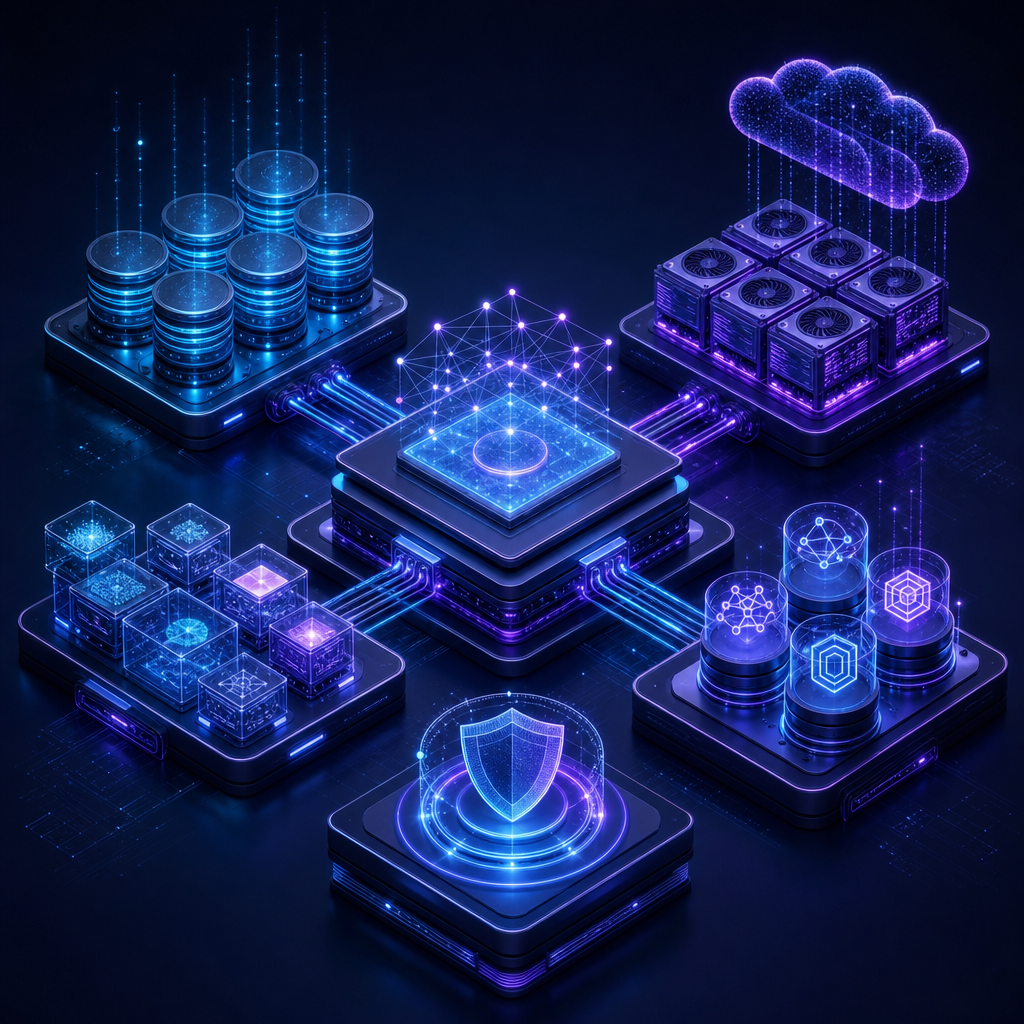
Connected AI platform architecture linking data, cloud services, models, and compute infrastructure
Enterprise AI platform foundations

The work

Engineering that holds up beyond the demo.

We engineer the infrastructure that lets teams build, deploy, and scale AI assets with industrial-grade reliability. The platform brings data foundations, elastic compute, MLOps, and governance together.

What we help you achieve

  • Faster movement from AI pilot to production
  • Lower platform duplication and total cost of ownership
  • Consistent delivery and operating controls across teams
  • Reusable access to data, compute, models, and evaluation
  • A modular platform that can absorb new models and workloads

Detailed capabilities

The work behind a dependable platform.

Explore the engineering areas that take this capability from a first technical decision to a stable, production-ready system.

01

Platform Strategy & Reference Architecture

The platform is shaped around the organization’s AI portfolio, operating model, risk, and economics.

  • Assess current data, tooling, models, environments, teams, bottlenecks, governance, and duplicated effort
  • Define boundaries for data, features, experiments, training, serving, applications, evaluation, and operations
  • Choose managed, open, cloud, on-premises, edge, or hybrid components around residency, latency, cost, and control
  • Create paved paths for common AI use cases while preserving extension points for specialized workloads
02

Data, Feature & Knowledge Foundations

AI teams need trusted, discoverable inputs with ownership and freshness built into the platform.

  • Provide catalogs, connectors, schemas, quality checks, lineage, access policies, and versioned data contracts
  • Support feature definitions, feature serving, point-in-time correctness, offline/online consistency, and reuse
  • Operationalize document, embedding, vector, metadata, retrieval, and knowledge-index pipelines
  • Make datasets, features, prompts, indexes, and evaluation sets discoverable with ownership and usage context
03

Compute, Model Services & Developer Experience

A platform should make the reliable path the easiest path for data scientists, engineers, and product teams.

  • Provision isolated development, training, evaluation, batch, real-time, streaming, and edge environments
  • Manage CPU/GPU/NPU capacity, queues, autoscaling, accelerator utilization, quotas, scheduling, and cost allocation
  • Offer model, prompt, retrieval, tool, and application templates with secure defaults and reusable SDKs
  • Expose self-service workflows for experiments, registries, deployment, monitoring, approval, and rollback
04

MLOps, LLMOps & Release Automation

The platform turns data and model changes into traceable, qualified releases.

  • Automate ingestion, validation, training, evaluation, prompt and retrieval testing, packaging, and promotion
  • Version code, data, features, models, prompts, indexes, dependencies, environments, and application contracts together
  • Support staged deployments, shadow traffic, canaries, A/B tests, rollback, retraining, and retirement
  • Generate release evidence for quality, safety, security, privacy, cost, provenance, and approval decisions
05

Governance, Security & Platform Operations

Enterprise AI needs shared controls that protect the organization without making every team reinvent them.

  • Apply identity, role and attribute-based access, tenant isolation, encryption, secrets boundaries, and network policy
  • Monitor service health, model quality, data drift, retrieval, cost, resource use, user feedback, and business outcomes
  • Centralize audit, lineage, risk acceptance, model cards, policy checks, incident response, and retention
  • Provide platform SLOs, support ownership, capacity planning, disaster recovery, and continuous improvement

Technical scope

Engineering detail from reset to runtime.

The work is designed around observable system behavior: what executes first, how resources are controlled, how failures are recovered, and how the platform proves it is ready.

01

Data & knowledge platform

  • Catalogs, connectors, schemas, quality, lineage, access policy, versioned contracts, feature definitions, and point-in-time correctness
  • Offline/online feature serving, document parsing, embeddings, vector indexes, metadata, retrieval, freshness, and evaluation sets
  • Discoverability, ownership, usage context, retention, residency, and governed reuse across teams
02

Compute & model services

  • Isolated development, training, evaluation, batch, real-time, streaming, edge, and hybrid environments
  • CPU/GPU/NPU scheduling, queues, autoscaling, quotas, accelerator utilization, resource limits, and cost allocation
  • Model, prompt, retrieval, tool, and application templates, SDKs, gateways, routing, caching, and fallback
03

MLOps & release

  • CI/CD/CT for code, data, features, prompts, models, indexes, applications, infrastructure, security, and evaluation
  • Registries, lineage, provenance, experiment tracking, quality gates, shadow, canary, A/B, rollback, retraining, and retirement
  • Release evidence for accuracy, groundedness, safety, privacy, security, performance, cost, and approvals
04

Enterprise controls

  • Identity, RBAC/ABAC, tenant isolation, encryption, secrets, network policy, data residency, retention, and audit
  • Health, quality, drift, retrieval, cost, resource, user feedback, business outcome, incident, and SLO monitoring
  • Risk registers, model cards, policy checks, disaster recovery, capacity planning, platform ownership, and support

Services and customer value

Technical work with a business reason.

Every engineering activity is tied to a decision your team needs to make: bring up faster, reduce risk, improve determinism, or prove production readiness.

01

AI platform strategy and reference architecture

Technical work

Assess the AI portfolio, data estate, teams, tooling, environments, risk, residency, latency, and economics, then define reusable platform boundaries and paved paths.

Customer benefit

The organization gets a coherent platform investment plan instead of another collection of disconnected AI tools.

02

Self-service data and model foundations

Technical work

Build governed catalogs, feature and knowledge services, experiment environments, registries, templates, SDKs, and secure access to reusable assets.

Customer benefit

Data scientists and product teams spend more time solving business problems and less time rebuilding plumbing.

03

Elastic AI compute and serving

Technical work

Provision training, evaluation, batch, real-time, streaming, edge, and hybrid runtimes with scheduling, autoscaling, quotas, routing, and cost allocation.

Customer benefit

Workloads receive needed capacity while the organization keeps control of latency, availability, residency, and spend.

04

Industrialized MLOps and LLMOps

Technical work

Automate data validation, experiment tracking, model/prompt/index packaging, evaluation, staged promotion, canaries, rollback, retraining, and retirement.

Customer benefit

Teams can release AI capabilities repeatedly with shared quality and safety expectations instead of one-off deployment processes.

05

AI governance and platform operations

Technical work

Implement identity, isolation, encryption, lineage, audit, policy checks, model cards, observability, SLOs, incident response, disaster recovery, and ownership.

Customer benefit

Enterprise controls become a reusable platform service that protects delivery speed rather than a late-stage blocker.

Why this matters for AI

Intelligence needs a dependable execution layer.

The difference between a successful AI pilot and an AI-driven company is the platform that makes good delivery repeatable. We build that factory around trusted data, elastic compute, automated lifecycle management, visible quality and cost, and shared governance so every new AI capability starts from a stronger baseline.

What you take forward

Clear outputs your team can build on.

  • AI platform assessment, portfolio map, operating model, reference architecture, capability roadmap, ownership model, and platform SLOs
  • Data and knowledge foundation with catalogs, connectors, quality, lineage, contracts, feature services, embeddings, indexes, and access controls
  • Self-service developer platform with environments, templates, SDKs, registries, experiment tracking, and reusable deployment paths
  • Elastic compute and serving configuration for training, evaluation, batch, real-time, streaming, edge, and hybrid workloads
  • MLOps/LLMOps delivery package with CI/CD/CT, evaluation, promotion, canary, rollback, retraining, retirement, and release evidence
  • Governance and operations handoff with identity, audit, observability, cost controls, incident runbooks, disaster recovery, and support model

Capability map

Built across the layers.

The right answer is usually a connected system of decisions, not a single isolated skill.

01

Data, feature, metadata, and knowledge foundations

02

Self-service model development and experiment environments

03

Elastic training, inference, and accelerator infrastructure

04

Industrialized CI/CD/CT, registries, and promotion gates

05

Model, prompt, data, cost, and quality observability

06

Identity, governance, security, and auditability

Keep exploring

See how the pieces connect.