Back to Eximietas Software

Digital & Intelligence Engineering · Domain-Specific AI Model Engineering

Custom Language Models & LLM Training

Purpose-built language models trained, adapted, and optimized for enterprise workflows and AI-enabled products.

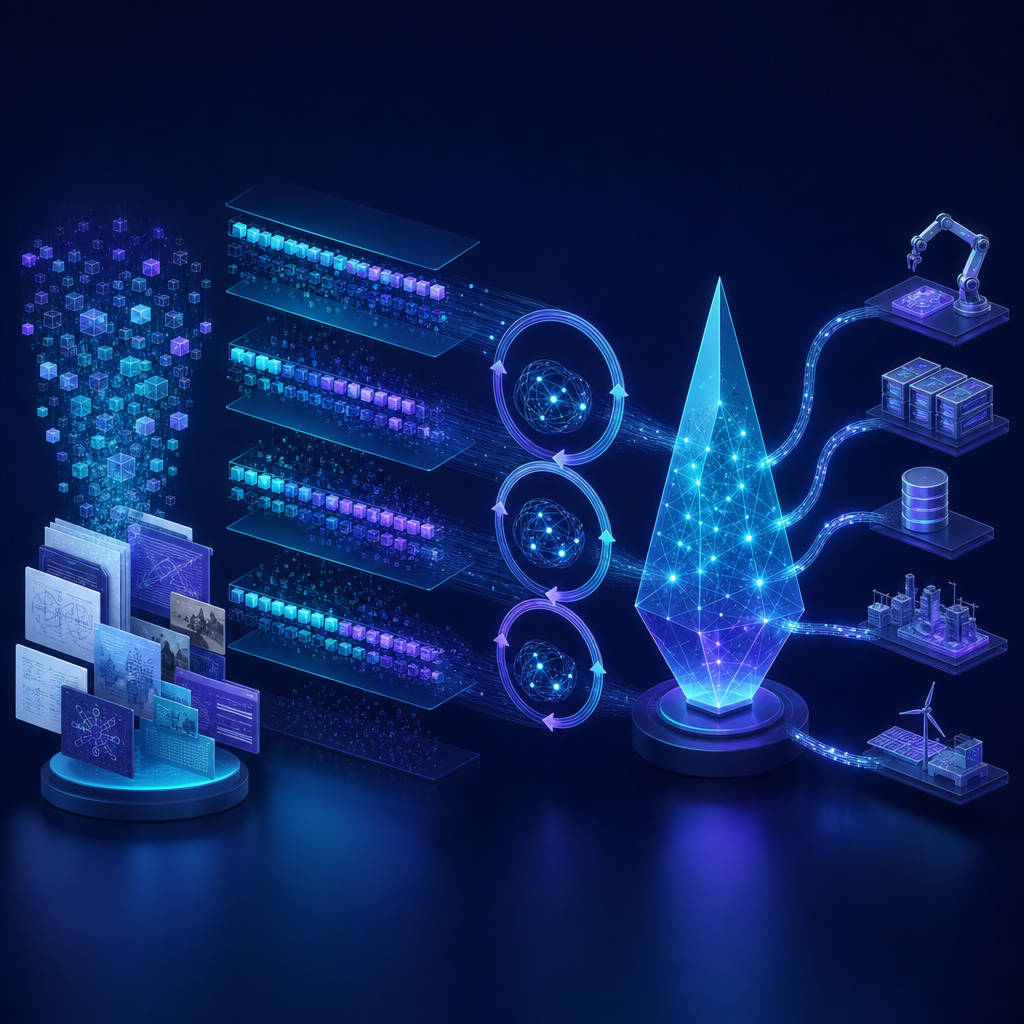
Domain-specific language model infrastructure connecting enterprise data, cloud intelligence, and product systems
Domain-specific model intelligence

The work

Engineering that holds up beyond the demo.

For enterprises with revenues above $1 billion and product companies selling AI-enabled products, we engineer language models around the data, workflows, risk, economics, and product experience that make their business distinct. Our Custom Language Models & LLM Training offering covers model strategy, domain data, continued pretraining, fine-tuning, distillation, evaluation, optimization, and production deployment—so teams can build intelligence they can control and improve.

What we help you achieve

  • A model strategy grounded in business value, data readiness, risk, latency, and total cost of ownership
  • Domain-specific model behavior aligned to proprietary terminology, workflows, and product experiences
  • Lower inference cost and latency through the right model size, tuning method, and runtime optimization
  • Greater control over sensitive data, model behavior, release decisions, and deployment environments
  • Measurable model quality with task-specific evaluation, safety checks, and release gates
  • A maintainable training-to-production lifecycle for models embedded in critical products and operations

Detailed capabilities

The work behind a dependable platform.

Explore the engineering areas that take this capability from a first technical decision to a stable, production-ready system.

01

Model Strategy & Opportunity Architecture

A clear decision framework prevents organizations from overbuilding a foundation model when a focused domain model can create more value.

  • Map product, operational, knowledge, and decision use cases to measurable model requirements
  • Choose between hosted models, open-weight models, retrieval, fine-tuning, continued pretraining, distillation, and from-scratch training
  • Define target model size, modalities, context, latency, throughput, residency, availability, and cost envelopes
  • Assess data readiness, ownership, licensing, privacy, security, annotation effort, compute demand, and operating capability
  • Create a staged roadmap with feasibility gates, baseline comparisons, investment decisions, and pilot-to-production criteria
02

Domain Data & Training Corpus Engineering

Model quality starts with a governed corpus that represents the language, knowledge, edge cases, and user intent of the domain.

  • Discover, classify, clean, deduplicate, normalize, and version documents, code, conversations, records, and product data
  • Design domain taxonomies, instruction datasets, preference pairs, task labels, and representative evaluation sets
  • Apply consent, licensing, PII handling, retention, residency, access control, and provenance requirements
  • Use synthetic data and targeted augmentation to cover rare events, long-tail workflows, and safe adversarial cases
  • Create data quality gates for contamination, leakage, imbalance, duplication, freshness, and train-test separation
03

Training, Adaptation & Model Development

Training methods are selected around the behavior the product needs, the data the organization owns, and the economics it can sustain.

  • Run continued pretraining for domain language, terminology, code, documents, and specialized knowledge
  • Apply supervised fine-tuning and instruction tuning for task behavior, structured outputs, tool use, and product workflows
  • Use parameter-efficient methods, adapters, low-rank updates, and controlled checkpoints to shorten iteration cycles
  • Develop preference optimization and human-feedback loops for helpfulness, style, ranking, refusal, and business-specific priorities
  • Track experiments, datasets, configurations, checkpoints, compute, metrics, and reproducibility evidence across training runs
04

Small Model Optimization & Product Integration

Smaller models can deliver better product economics when they are deliberately optimized for the task, runtime, and user experience.

  • Distill capabilities from larger teacher models into smaller student models with task and safety checks
  • Apply quantization, pruning, sparsity, compilation, batching, caching, and memory optimization
  • Tune for real-time, batch, streaming, edge, mobile, and on-device inference constraints
  • Integrate model APIs and SDKs with product identity, entitlements, telemetry, human review, and fallback behavior
  • Benchmark quality, latency, throughput, accelerator utilization, memory, power, and cost against credible baselines
05

Evaluation, Safety & Enterprise Governance

A model is ready when its behavior is measurable, explainable, safe enough for its context, and governed by accountable owners.

  • Build golden datasets, task-specific benchmarks, reference answers, rubrics, edge cases, and regression suites
  • Measure accuracy, groundedness, relevance, completeness, structured-output validity, calibration, latency, and cost
  • Test hallucination, prompt injection, data exfiltration, harmful content, bias, privacy, copyright, and misuse risks
  • Establish model cards, data lineage, approval gates, risk acceptance, access policies, audit trails, and release evidence
  • Use shadow, canary, red-team, human review, and rollback controls before expanding model exposure
06

Production Training & Model Operations

The model becomes a durable enterprise capability when training, serving, monitoring, and improvement are operated as one lifecycle.

  • Deploy to cloud, private-cloud, on-premise, hybrid, edge, or device environments based on the product and data boundary
  • Operate versioned model, dataset, tokenizer, prompt, adapter, evaluation, runtime, and application contracts
  • Monitor quality, drift, data changes, user feedback, latency, throughput, availability, resource use, and inference spend
  • Automate retraining, evaluation, promotion, deprecation, rollback, incident response, and model retirement
  • Create operating ownership, SLOs, support procedures, capacity plans, and continuous improvement loops

Technical scope

Engineering detail from reset to runtime.

The work is designed around observable system behavior: what executes first, how resources are controlled, how failures are recovered, and how the platform proves it is ready.

01

Strategy & architecture

  • Use-case value, data readiness, build-versus-adapt decisions, hosted and open models, model sizing, modalities, context, residency, latency, availability, and cost
  • Training strategy across retrieval, fine-tuning, continued pretraining, preference optimization, distillation, and from-scratch model development
  • Product and operating boundaries for data, training, evaluation, serving, identity, human review, audit, and ownership
02

Data & training systems

  • Corpus discovery, parsing, cleaning, deduplication, normalization, taxonomy, annotation, instruction data, preference pairs, synthetic data, and provenance
  • PII, licensing, consent, access, retention, residency, contamination, leakage, imbalance, freshness, and train-test separation controls
  • Distributed training, experiment tracking, checkpointing, dataset versioning, reproducibility, compute allocation, and artifact registries
03

Model adaptation & optimization

  • Continued pretraining, supervised fine-tuning, instruction tuning, parameter-efficient adaptation, adapters, preference optimization, and controlled checkpoints
  • Distillation, quantization, pruning, sparsity, compilation, batching, caching, memory optimization, and accelerator-aware serving
  • Cloud, private-cloud, on-premise, hybrid, edge, mobile, and on-device runtime patterns
04

Evaluation & governance

  • Golden datasets, reference answers, rubrics, regression suites, accuracy, groundedness, relevance, completeness, structured outputs, calibration, latency, and cost
  • Red teaming for hallucination, injection, exfiltration, harmful content, bias, privacy, copyright, misuse, and product-specific failure modes
  • Model cards, lineage, approvals, risk acceptance, access policy, audit, shadow, canary, human review, rollback, and release evidence
05

Production lifecycle

  • Versioned models, datasets, tokenizers, prompts, adapters, evaluations, runtimes, application contracts, and deployment configuration
  • Monitoring for quality, drift, feedback, latency, throughput, availability, resource use, spend, and business outcomes
  • Retraining, promotion, deprecation, retirement, incident response, SLOs, capacity planning, support, and continuous improvement
06

Product & enterprise integration

  • Model APIs, SDKs, gateways, structured outputs, tool contracts, identity, entitlements, tenant isolation, and human-review workflows
  • Integration with product interfaces, enterprise systems, knowledge services, event pipelines, analytics, telemetry, and customer support
  • Fallback, graceful degradation, abuse controls, feedback capture, user guidance, adoption measurement, and model-driven business outcomes

Services and customer value

Technical work with a business reason.

Every engineering activity is tied to a decision your team needs to make: bring up faster, reduce risk, improve determinism, or prove production readiness.

01

Custom model strategy and architecture

Technical work

Translate business and product requirements into a model roadmap covering hosted versus owned models, retrieval, fine-tuning, continued pretraining, distillation, model size, deployment boundary, and economics.

Customer benefit

Leaders invest in the smallest practical model capability that can create differentiated value, rather than carrying unnecessary training and operating cost.

02

Domain data and training corpus engineering

Technical work

Build governed corpora, instruction datasets, preference data, evaluation sets, synthetic data, taxonomies, quality gates, lineage, and privacy controls from enterprise and product data.

Customer benefit

Models learn the organization’s language and workflows from data that is traceable, usable, and safe to bring into a training lifecycle.

03

LLM training and domain adaptation

Technical work

Run continued pretraining, supervised fine-tuning, instruction tuning, parameter-efficient adaptation, preference optimization, experiment tracking, and reproducible checkpoint management.

Customer benefit

Teams gain model behavior tuned to their domain without treating every AI requirement as a generic prompt-engineering problem.

04

Small language model optimization

Technical work

Distill, quantize, prune, compile, and benchmark models for product-specific quality, latency, throughput, memory, power, and inference-cost targets.

Customer benefit

AI-enabled products can deliver responsive experiences and healthier unit economics across cloud, private, edge, mobile, and device runtimes.

05

Model evaluation and responsible AI

Technical work

Create task benchmarks, golden datasets, regression suites, red-team cases, safety checks, model cards, risk controls, approvals, and release evidence.

Customer benefit

Product and enterprise stakeholders can see whether a model is ready, where it fails, and who is accountable for its use.

06

Production model lifecycle engineering

Technical work

Connect training, registries, deployment, monitoring, feedback, retraining, canaries, rollback, incident response, governance, and retirement into an operating lifecycle.

Customer benefit

The model becomes a maintainable production capability rather than a one-time research artifact.

Why this matters for AI

Intelligence needs a dependable execution layer.

The most valuable enterprise model is not always the largest model. It is the model whose behavior, economics, privacy, latency, and deployment boundary fit the job. We combine Custom Language Models & LLM Training with Domain-Specific AI Model Engineering so large enterprises and AI-enabled product companies can turn proprietary data and differentiated workflows into intelligence they can measure, operate, and own.

What you take forward

Clear outputs your team can build on.

  • Model opportunity assessment, use-case map, build-versus-adapt decision, target architecture, economics, risk profile, and phased roadmap
  • Governed training corpus package with source inventory, taxonomy, cleaning, deduplication, annotation, synthetic data, privacy, licensing, provenance, and quality gates
  • Reproducible training and adaptation pipeline with datasets, configurations, checkpoints, experiment tracking, compute allocation, and artifact lineage
  • Optimized model package with fine-tuned or pretrained checkpoints, adapters, distillation, quantization, runtime benchmarks, and deployment artifacts
  • Evaluation and responsible-AI pack with golden datasets, task metrics, regression results, red-team findings, model cards, limitations, and approval evidence
  • Production lifecycle handoff with serving configuration, monitoring, feedback, retraining, promotion, rollback, incident, support, and retirement runbooks

Capability map

Built across the layers.

The right answer is usually a connected system of decisions, not a single isolated skill.

01

Model selection, architecture, sizing, and build-versus-adapt strategy

02

Domain data curation, governance, synthetic data, and training corpus development

03

Continued pretraining, supervised fine-tuning, instruction tuning, and preference optimization

04

Parameter-efficient adaptation, adapters, distillation, pruning, and quantization

05

Task-specific evaluation, red teaming, safety, privacy, and responsible AI controls

06

Cloud, private-cloud, on-premise, edge, and on-device model serving

07

Model registry, lineage, experiment tracking, release automation, and rollback

08

Inference optimization for quality, throughput, latency, memory, and cost

Keep exploring

See how the pieces connect.